Back to Showcase
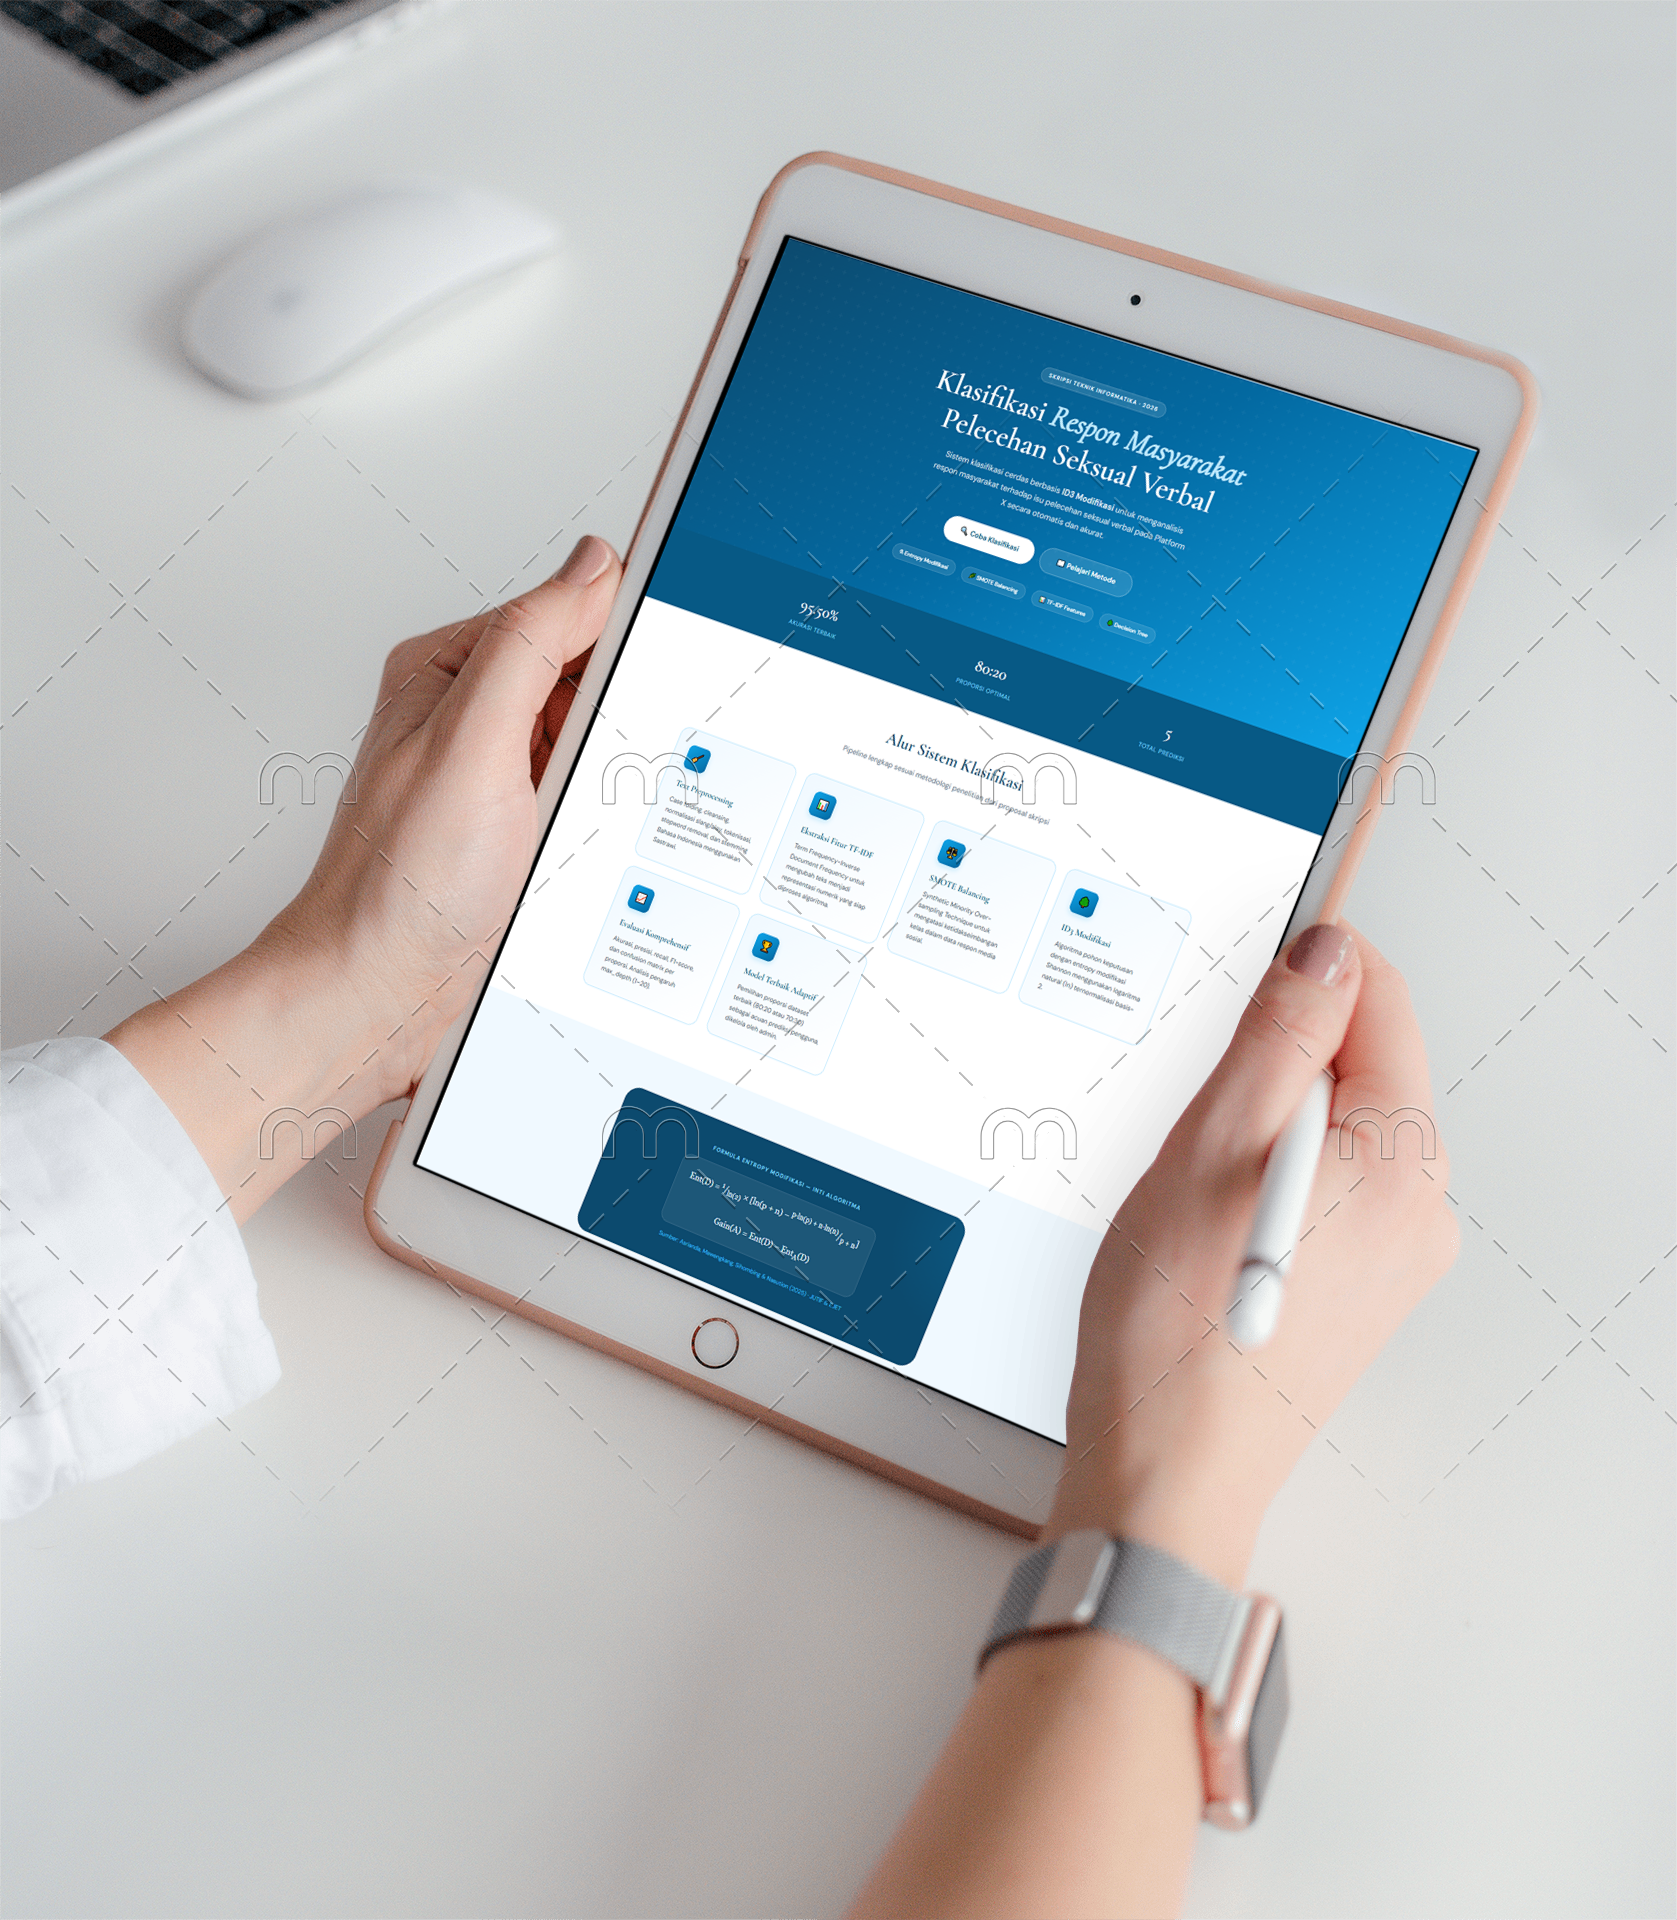
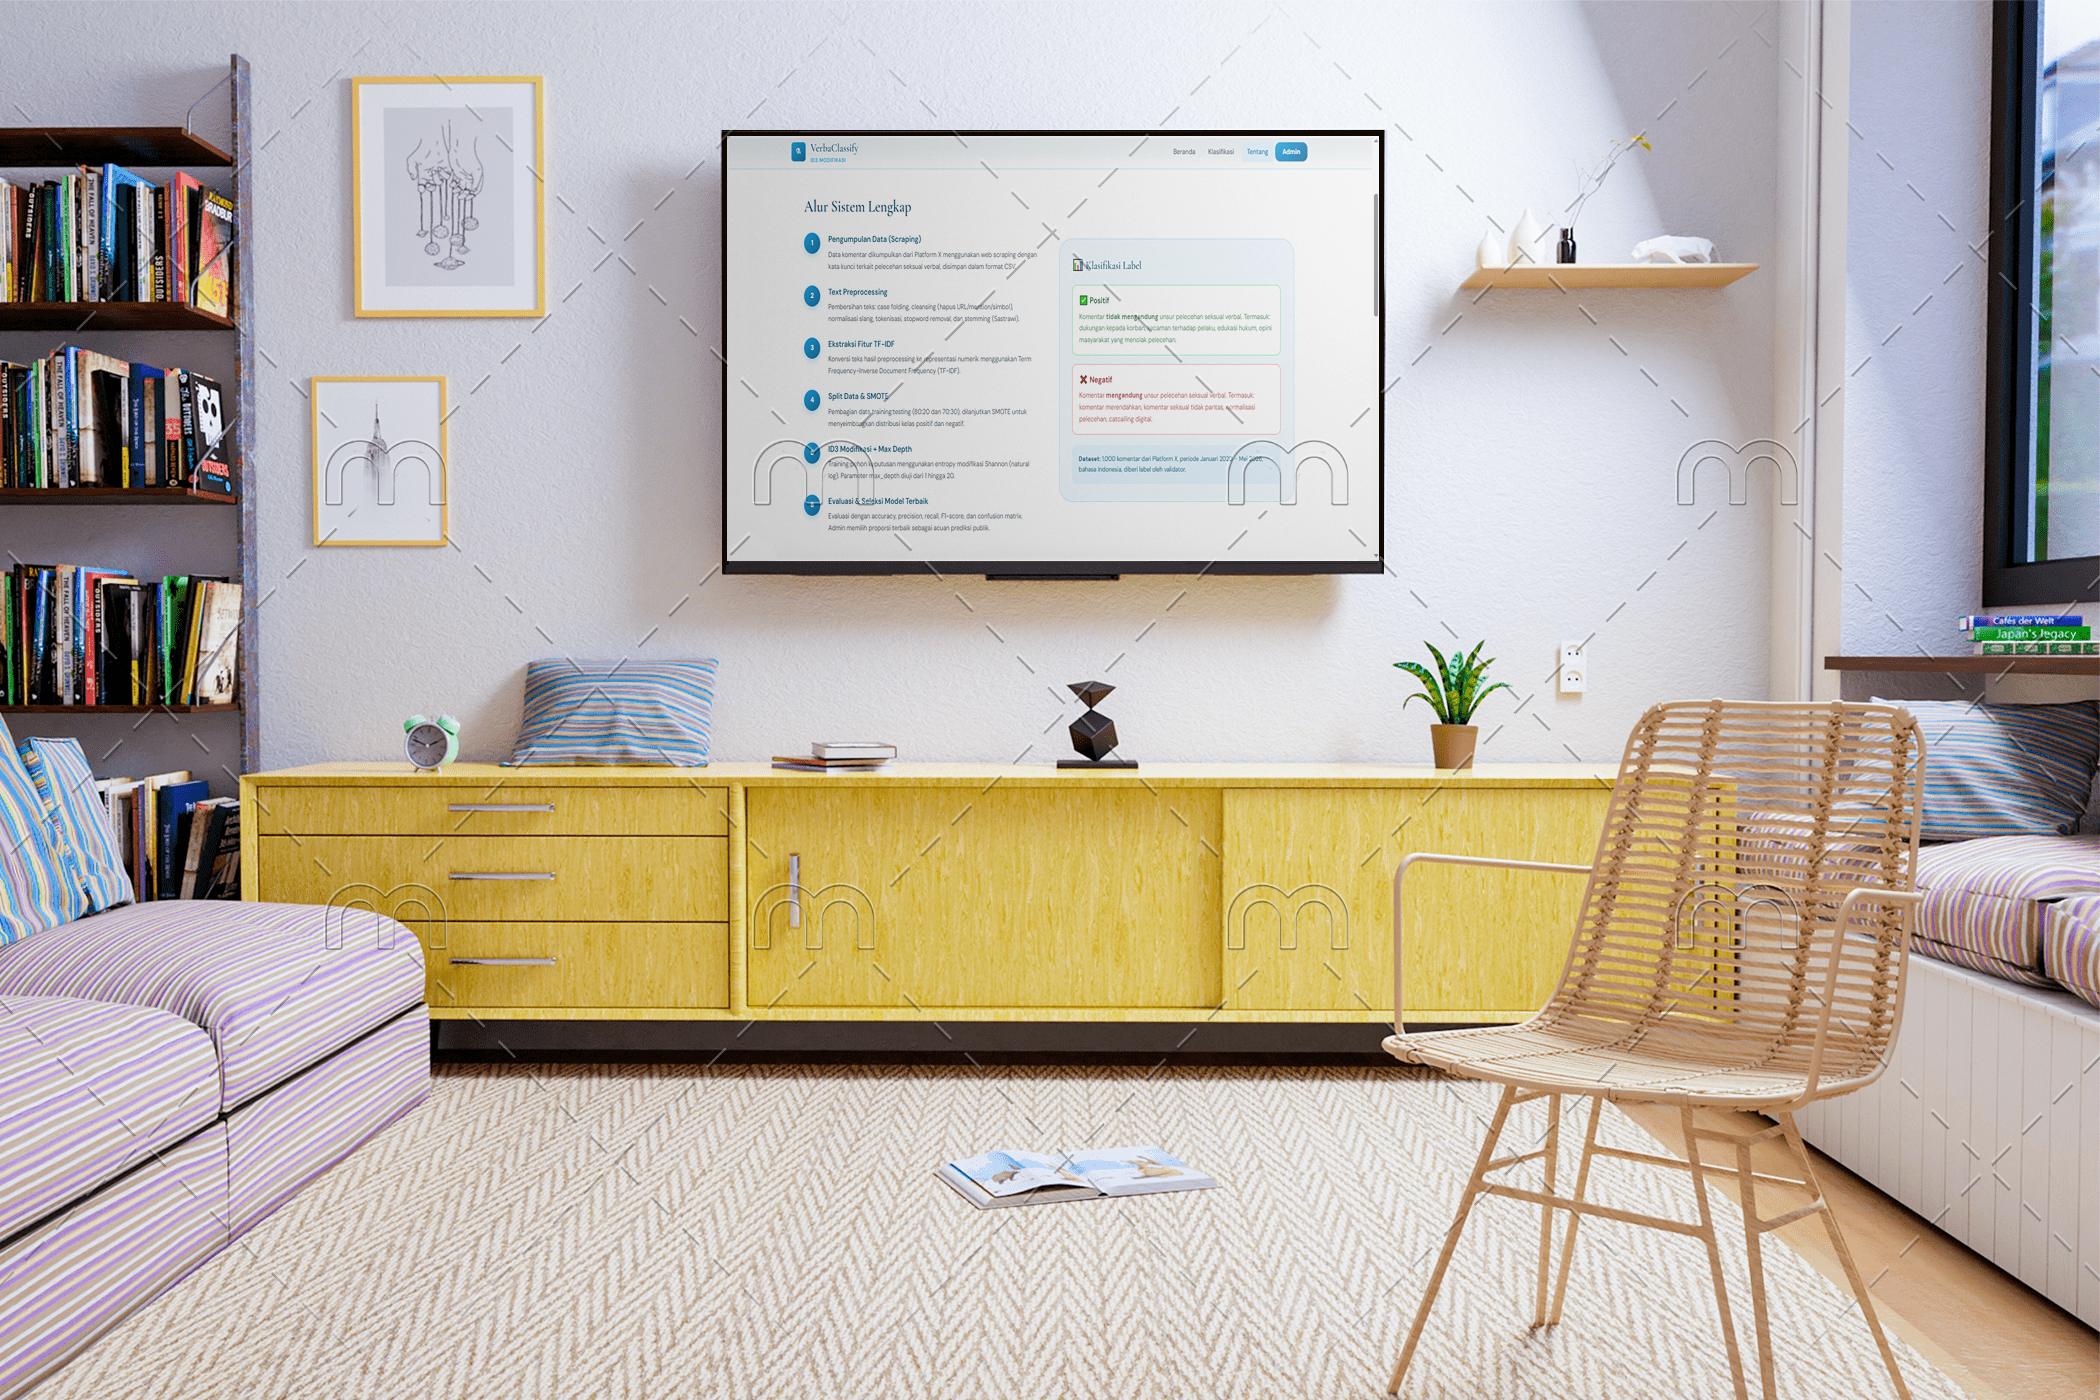
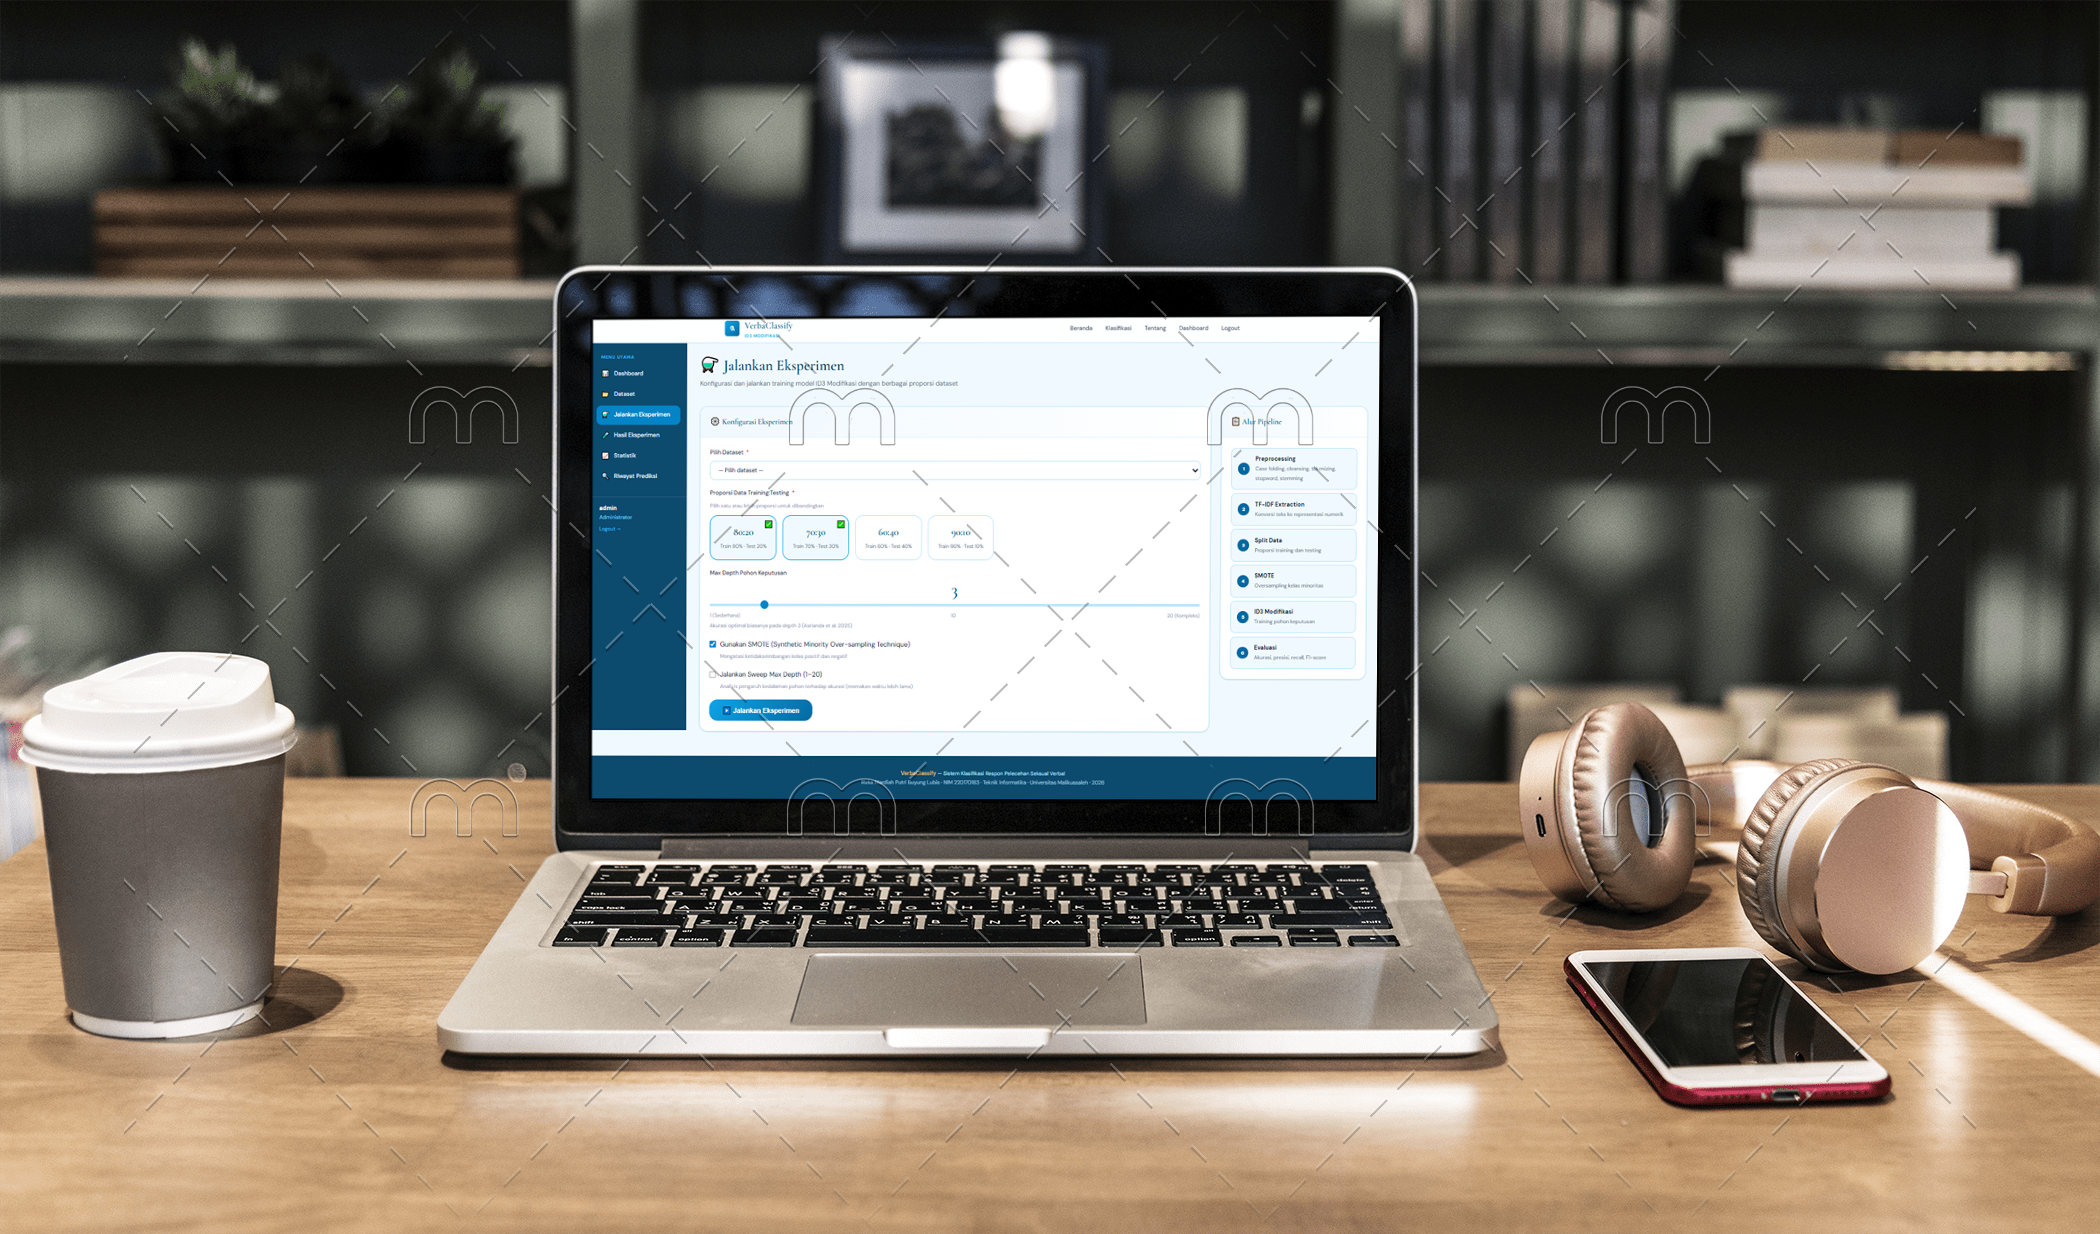
VerbaClassify is a web-based information system developed to classify public opinions related to verbal harassment on the X (formerly Twitter) platform using machine learning. The system enables administrators to manage the complete machine learning pipeline—from dataset preparation and preprocessing to model training and evaluation—while providing a public-facing interface where users can classify new text using the best-performing trained model.
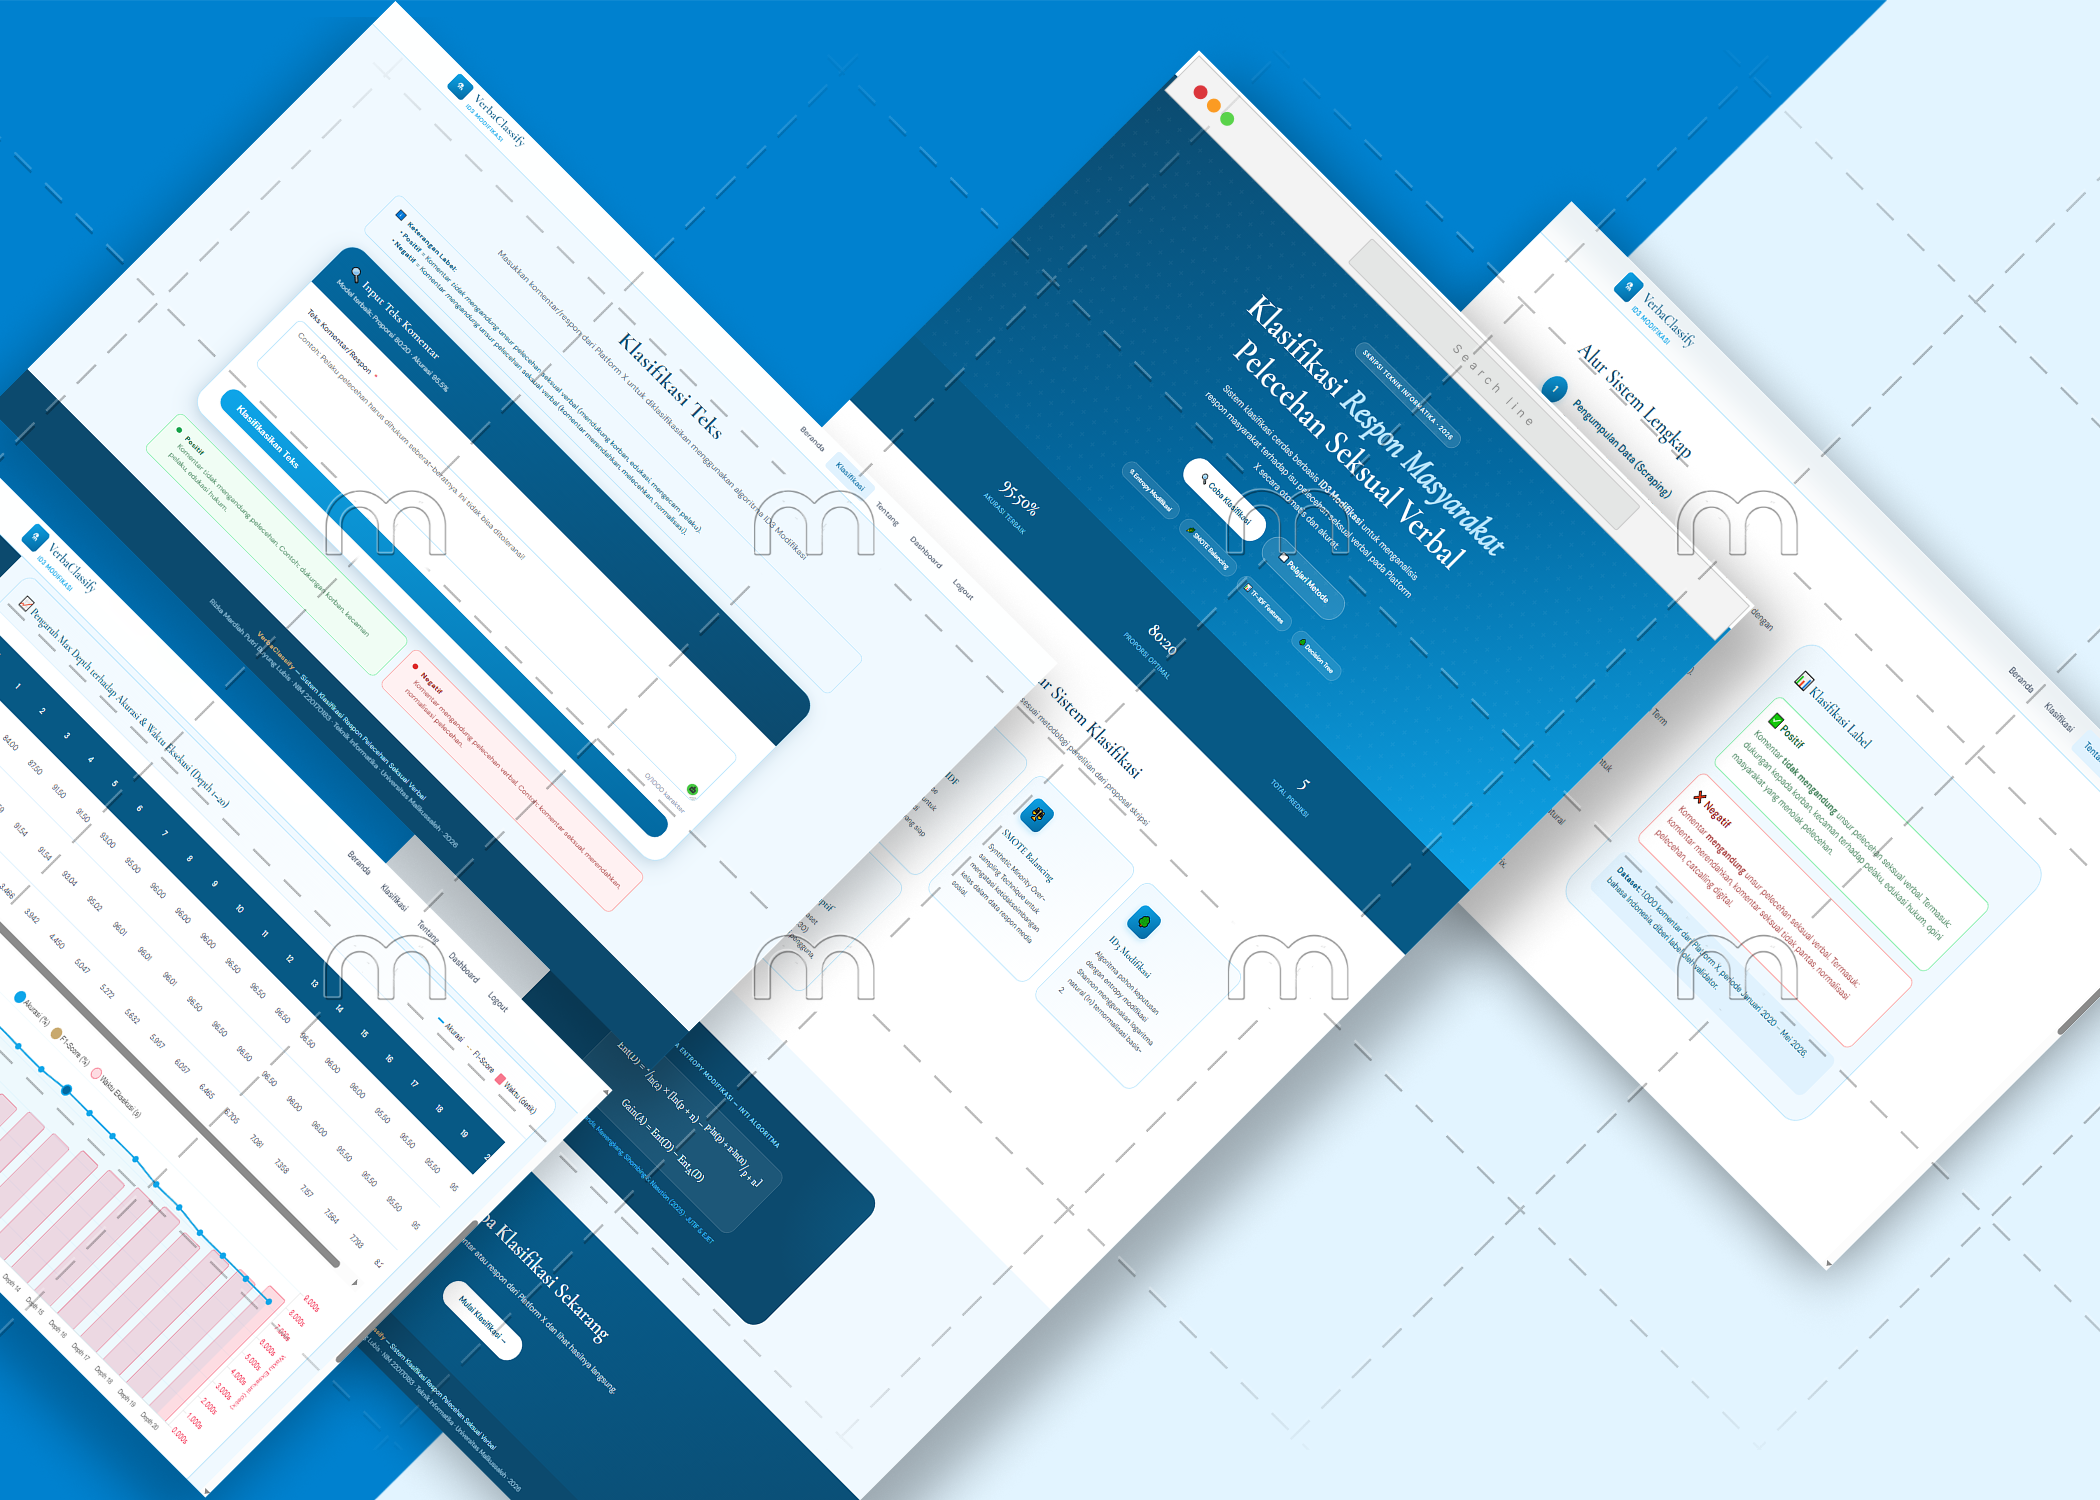
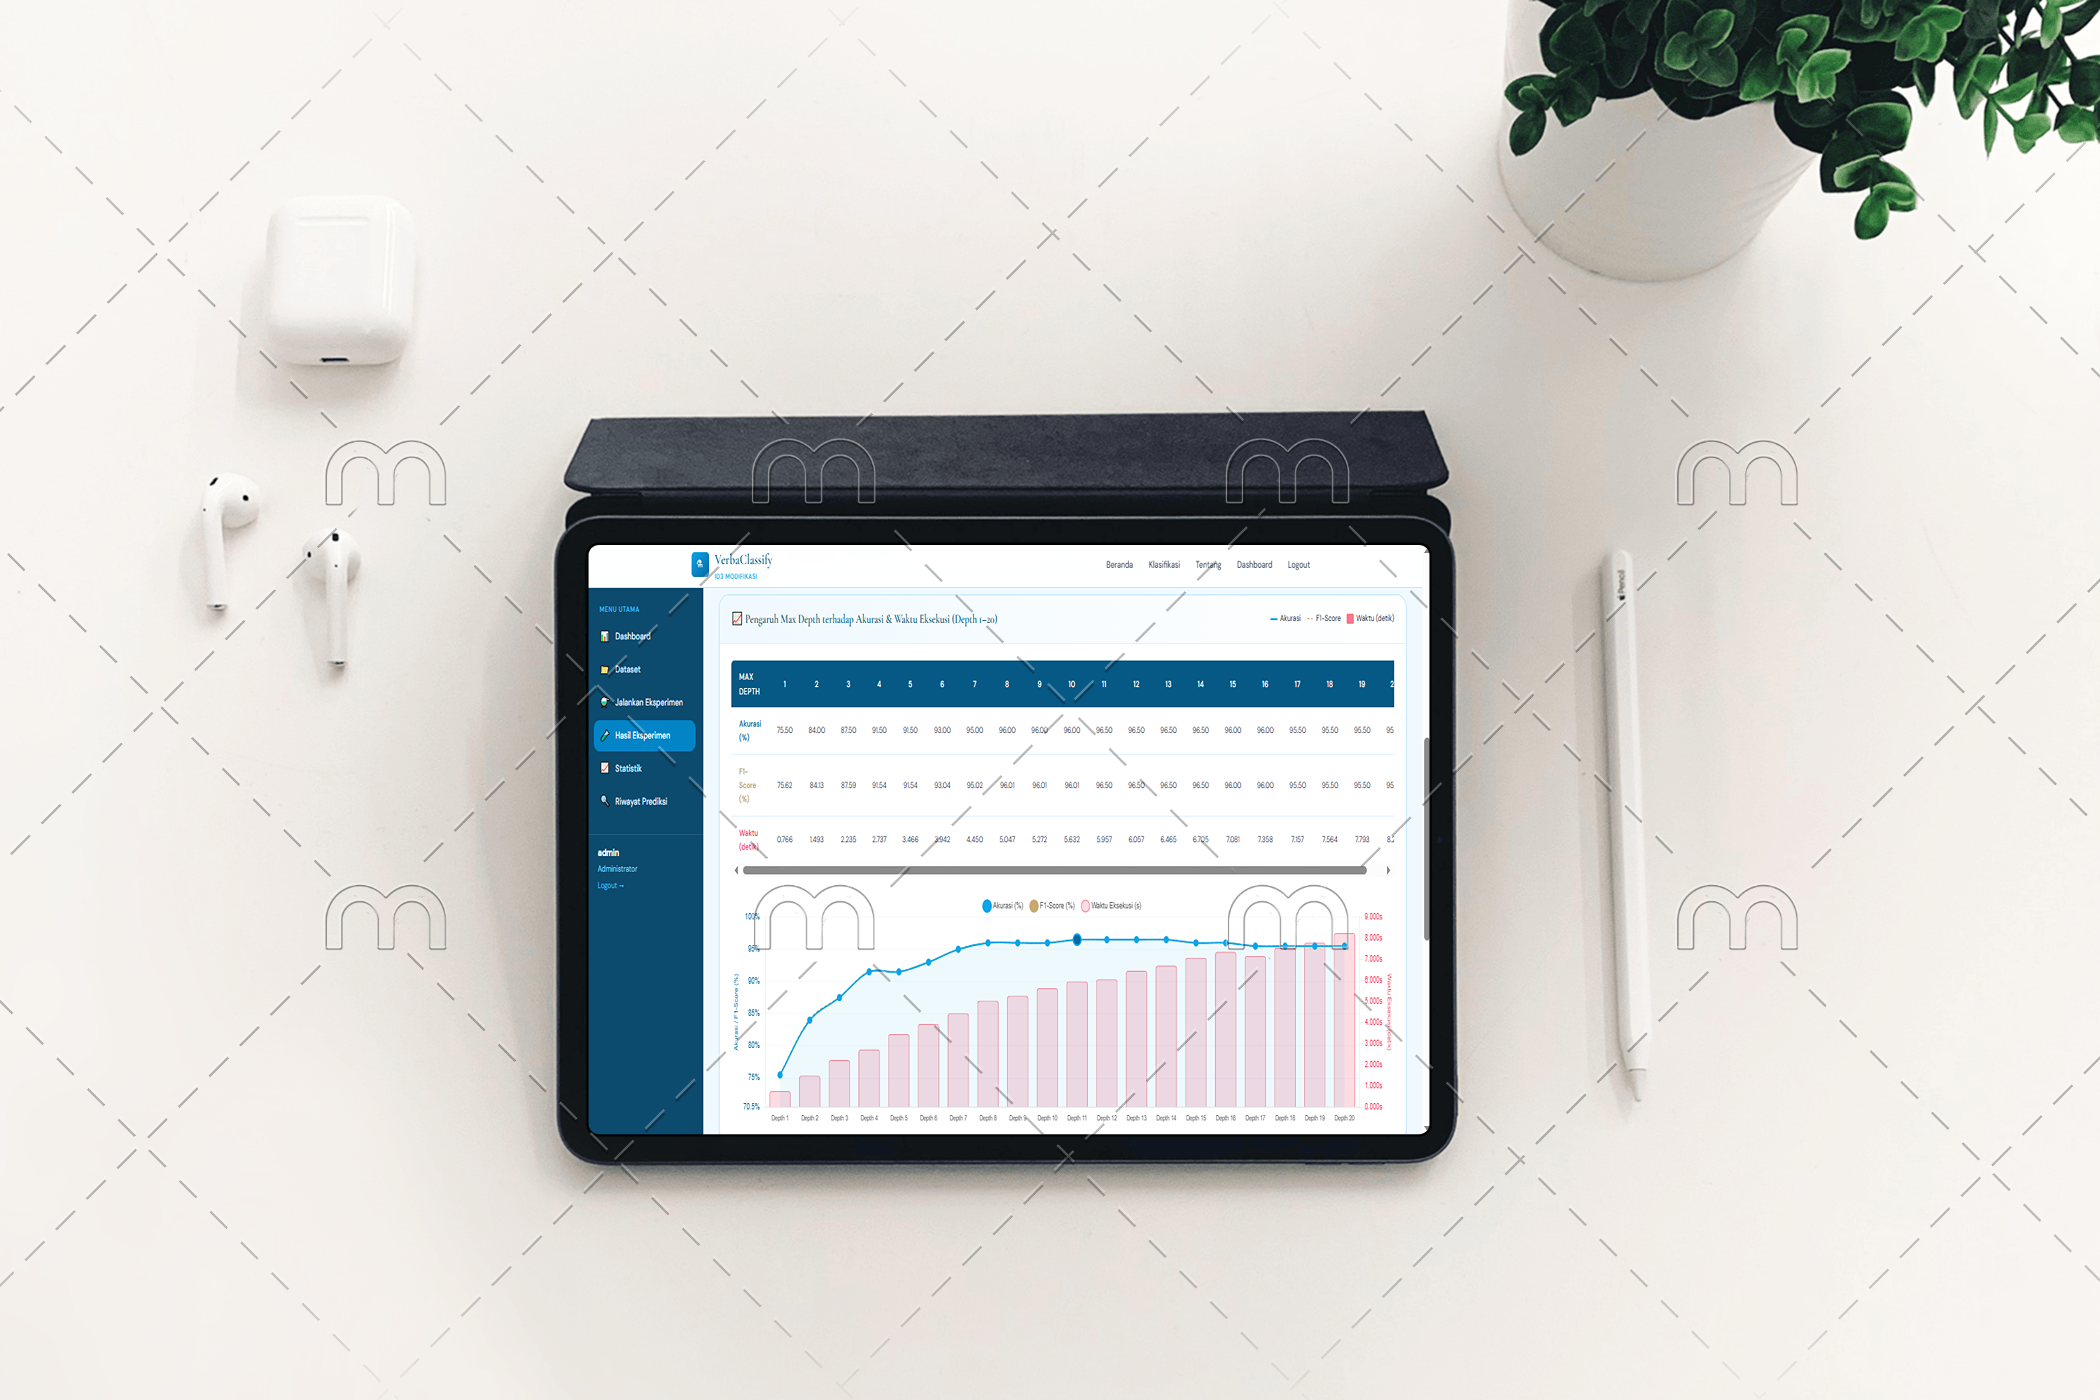
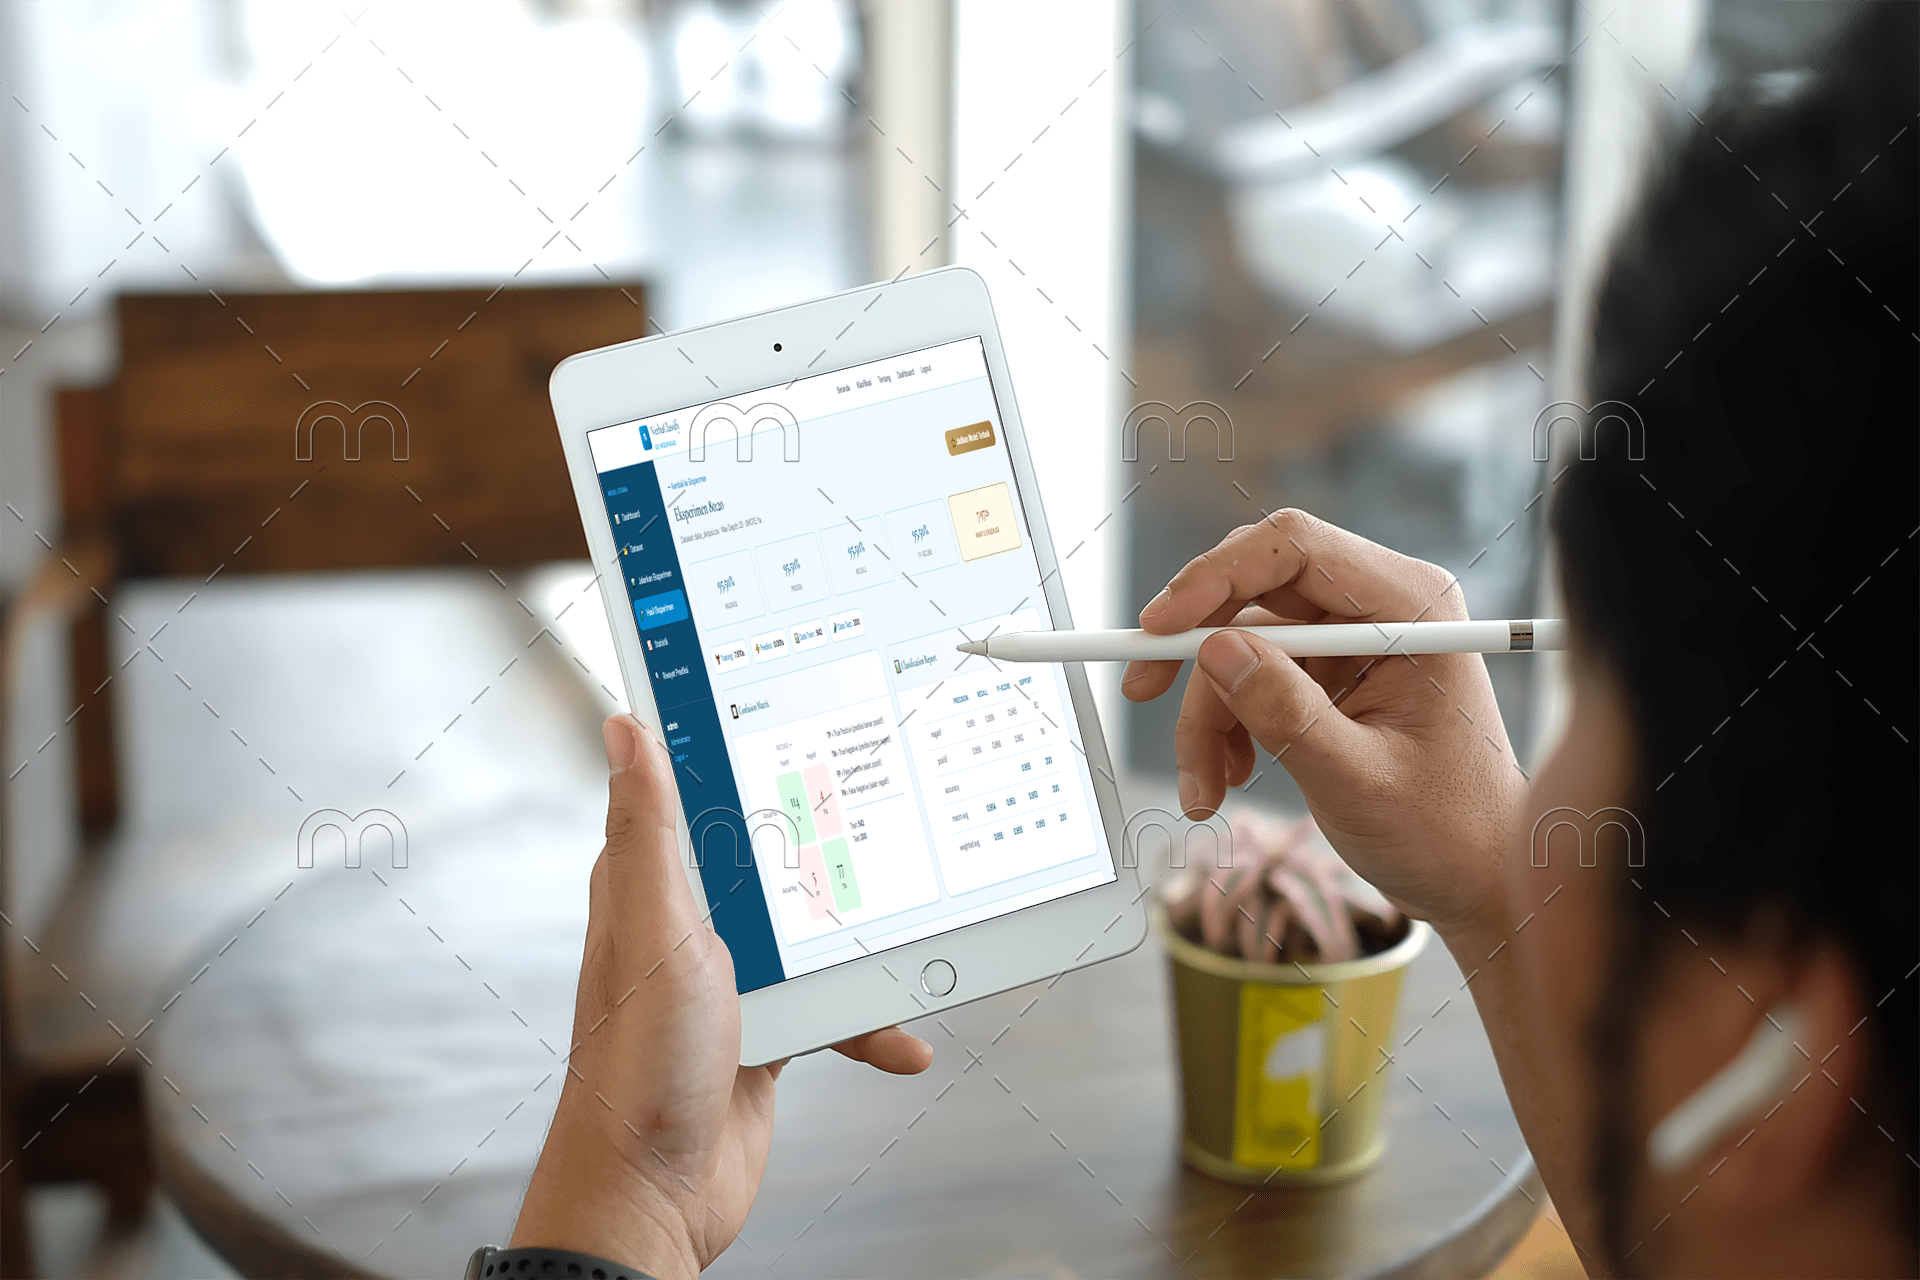
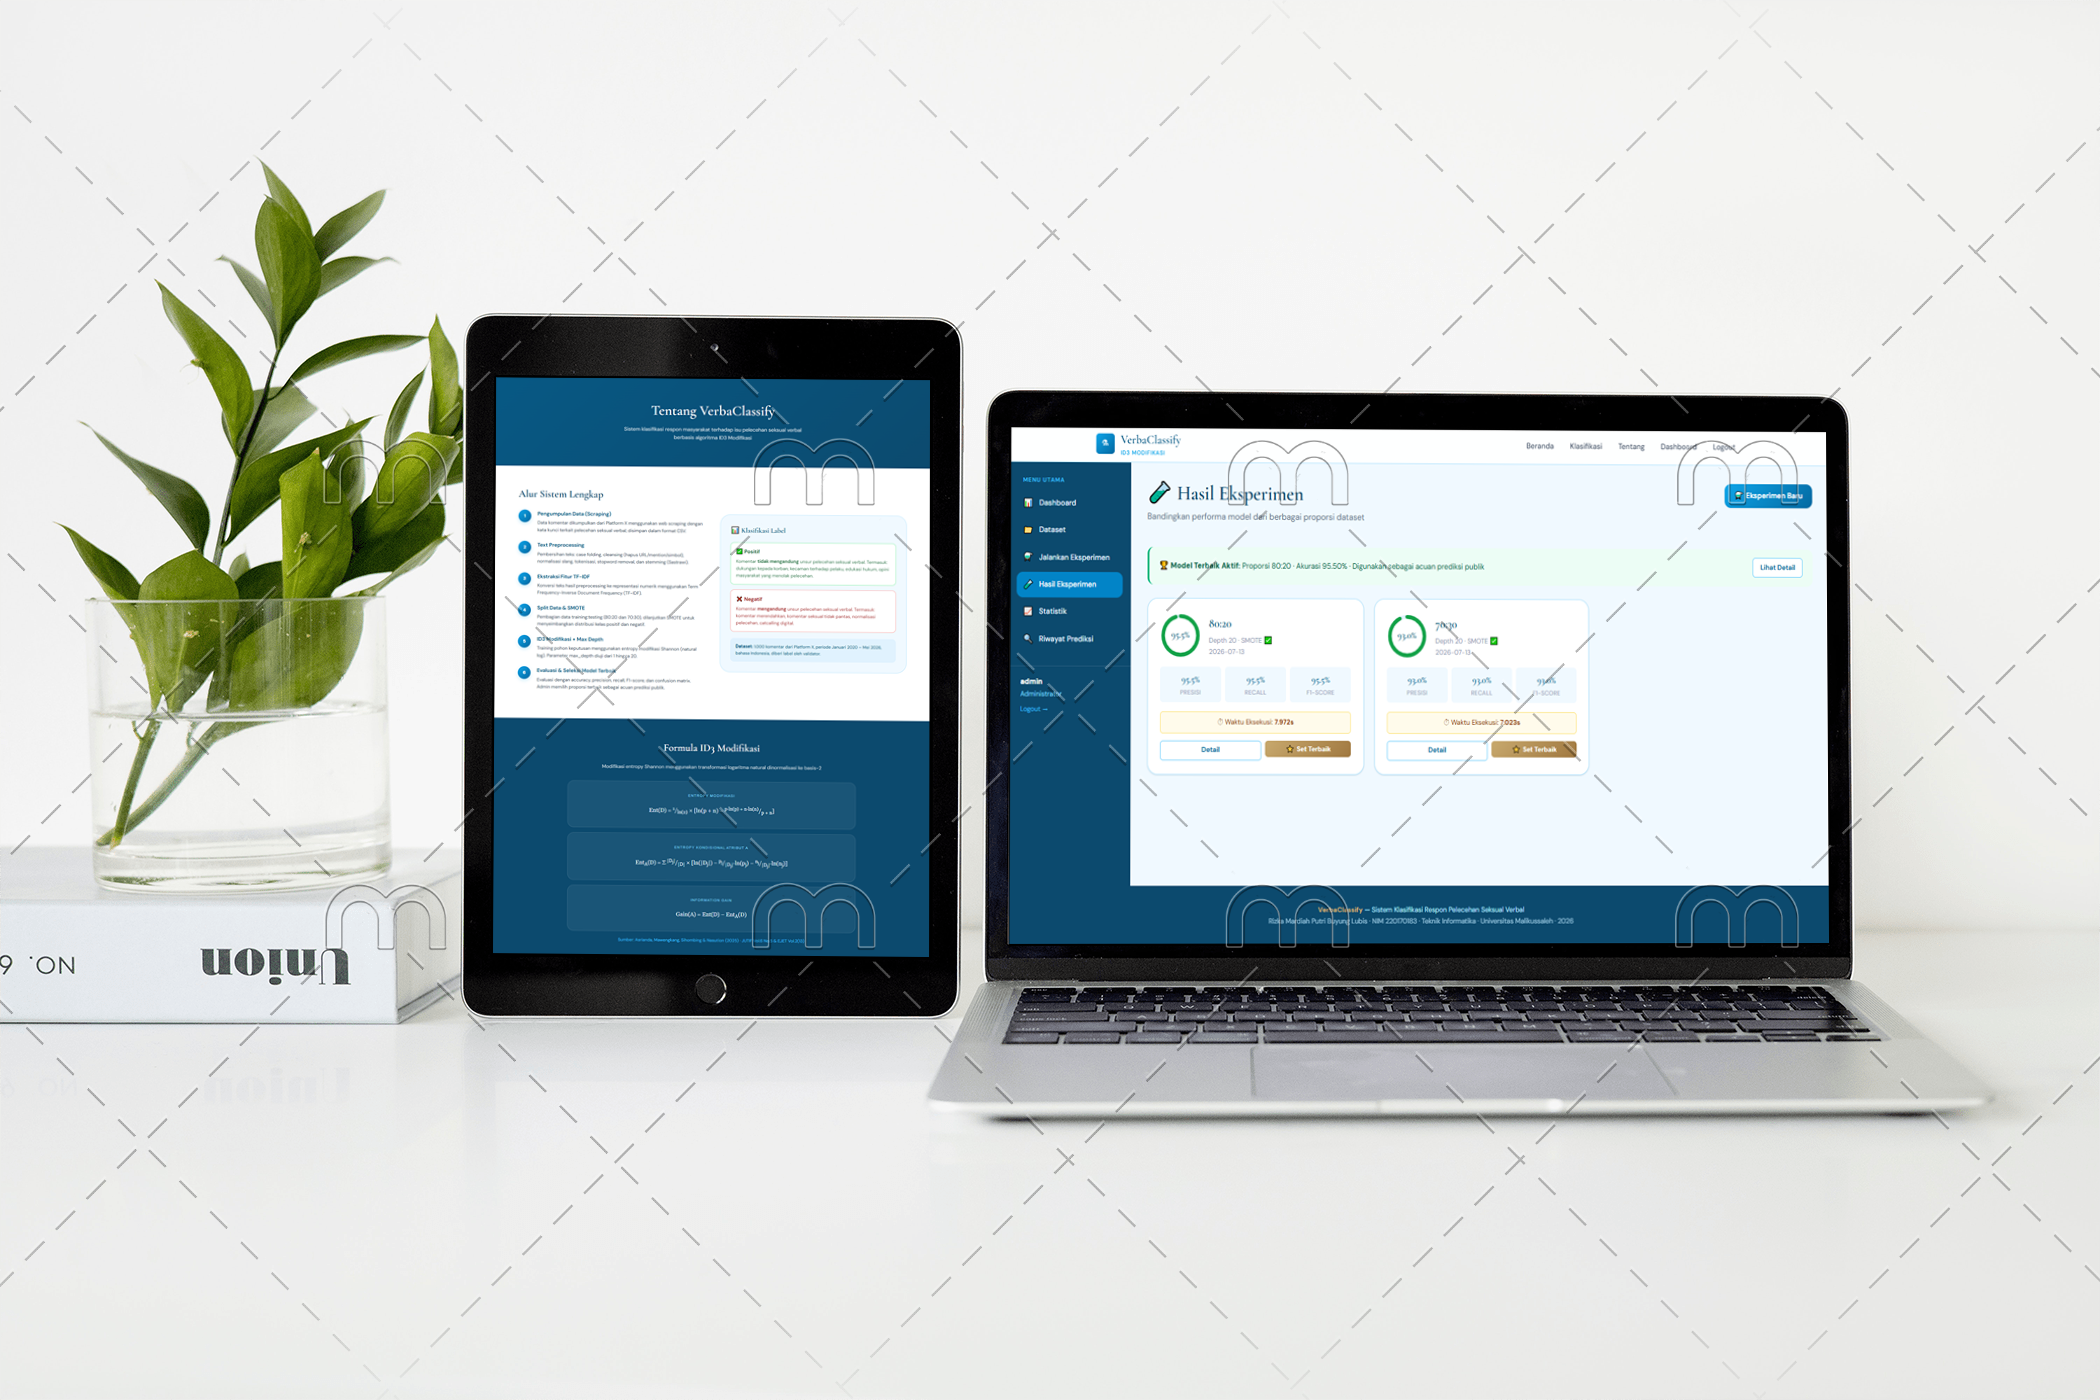
The application consists of two interfaces: an Administrator panel and a public landing page. Administrators manage a dataset of 1,000 labeled comments, perform text preprocessing, apply TF-IDF feature extraction, address class imbalance using SMOTE (Synthetic Minority Over-sampling Technique), train and evaluate an Improved Iterative Instance Adjustment (I3) Modified classification model, and deploy the best-performing model. Users can access the landing page to classify text related to verbal harassment using the deployed model.


Project Summary
The application consists of two interfaces: an Administrator panel and a public landing page. Administrators manage a dataset of 1,000 labeled comments, perform text preprocessing, apply TF-IDF feature extraction, address class imbalance using SMOTE (Synthetic Minority Over-sampling Technique), train and evaluate an Improved Iterative Instance Adjustment (I3) Modified classification model, and deploy the best-performing model. Users can access the landing page to classify text related to verbal harassment using the deployed model.
System Galleries